Test Data Generator
Dummy Dataset Generation
Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Use when creating test data, building mock datasets, or generating sample data for development and…
---
name: dummy-dataset
description: "Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Use when creating test data, building mock datasets, or generating sample data for development and demos."
---
# Dummy Dataset Generation

Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Creates executable scripts or direct data files for immediate use.

**Use when:** Creating test data, generating sample datasets, building realistic mock data for development, or populating test environments.

**Arguments:**
- `$PRODUCT`: The product or system name
- `$DATASET_TYPE`: Type of data (e.g., customer feedback, transactions, user profiles)
- `$ROWS`: Number of rows to generate (default: 100)
- `$COLUMNS`: Specific columns or fields to include
- `$FORMAT`: Output format (CSV, JSON, SQL, Python script)
- `$CONSTRAINTS`: Additional constraints or business rules
Overview
Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Creates executable scripts or direct data files for immediate use.
What you get
- Ready-to-execute Python script OR direct data file
- CSV file with proper headers and formatting
- JSON file with valid structure and types
- SQL INSERT statements for database population
- Data validation and constraint compliance
- Realistic, business-appropriate values
Manual install (npx, ZIP)
npx skills add phuryn/pm-skills --skill dummy-dataset -g -a claude-codenpx degit phuryn/pm-skills/pm-execution/skills/dummy-dataset#main ~/.claude/skills/dummy-datasetConnects with Agent Alley MCP · agentalley.io/mcp
Files included
SKILL.md3.8 KB
Read SKILL.md here
Show the full text115 lines
Dummy Dataset Generation
Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Creates executable scripts or direct data files for immediate use.
Use when: Creating test data, generating sample datasets, building realistic mock data for development, or populating test environments.
Arguments:
$PRODUCT: The product or system name$DATASET_TYPE: Type of data (e.g., customer feedback, transactions, user profiles)$ROWS: Number of rows to generate (default: 100)$COLUMNS: Specific columns or fields to include$FORMAT: Output format (CSV, JSON, SQL, Python script)$CONSTRAINTS: Additional constraints or business rules
Step-by-Step Process
- Identify dataset type - Understand the data domain
- Define column specifications - Names, data types, and value ranges
- Determine row count - How many sample records needed
- Select output format - CSV, JSON, SQL INSERT, or Python script
- Apply realistic patterns - Ensure data looks authentic and valid
- Add business constraints - Respect business logic and relationships
- Generate or script data - Create executable output
- Validate output - Ensure data quality and completeness
Template: Python Script Output
import csv
import json
from datetime import datetime, timedelta
import random

# Configuration
ROWS = $ROWS
FILENAME = "$DATASET_TYPE.csv"

# Column definitions with realistic value generators
columns = {
    "id": "auto-increment",
    "name": "first_last_name",
    "email": "email",
    "created_at": "timestamp",
    # Add more columns...
}

def generate_dataset():
    """Generate realistic dummy dataset"""
    data = []
    for i in range(1, ROWS + 1):
        record = {
            "id": f"U{i:06d}",
            # Generate values based on column definitions
        }
        data.append(record)
    return data

def save_as_csv(data, filename):
    """Save dataset as CSV"""
    with open(filename, 'w', newline='') as f:
        writer = csv.DictWriter(f, fieldnames=data[0].keys())
        writer.writeheader()
        writer.writerows(data)

if __name__ == "__main__":
    dataset = generate_dataset()
    save_as_csv(dataset, FILENAME)
    print(f"Generated {len(dataset)} records in {FILENAME}")
Example Dataset Specification
Dataset Type: Customer Feedback
Columns:
- feedback_id (auto-increment, U001, U002...)
- customer_name (realistic names)
- email (valid email format)
- feedback_date (dates last 90 days)
- rating (1-5 stars)
- category (Bug, Feature Request, Complaint, Praise)
- text (realistic feedback)
- product (electronics, clothing, home)
Constraints:
- Ratings skewed: 40% 5-star, 30% 4-star, 20% 3-star, 10% 1-2 star
- Bug category only with ratings 1-3
- Feature requests only with ratings 3-5
- Email domains realistic (gmail, yahoo, company.com)
Output Deliverables
- Ready-to-execute Python script OR direct data file
- CSV file with proper headers and formatting
- JSON file with valid structure and types
- SQL INSERT statements for database population
- Data validation and constraint compliance
- Realistic, business-appropriate values
- Documentation of data generation logic
- Quick-start instructions for using the dataset
Output Formats
CSV: Flat tabular format, easy to import into spreadsheets and databases
JSON: Nested structure, ideal for APIs and NoSQL databases
SQL: INSERT statements, directly executable on relational databases
Python Script: Executable generator for custom or large datasets
| 1 | |
| 2 | name dummy-dataset |
| 3 | description "Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Use when creating test data, building mock datasets, or generating sample data for development and demos." |
| 4 | |
| 5 | # Dummy Dataset Generation |
| 6 | |
| 7 | Generate realistic dummy datasets for testing with customizable columns, constraints, and output formats (CSV, JSON, SQL, Python script). Creates executable scripts or direct data files for immediate use. |
| 8 | |
| 9 | **Use when:** Creating test data, generating sample datasets, building realistic mock data for development, or populating test environments. |
| 10 | |
| 11 | **Arguments:** |
| 12 | `$PRODUCT`: The product or system name |
| 13 | `$DATASET_TYPE`: Type of data (e.g., customer feedback, transactions, user profiles) |
| 14 | `$ROWS`: Number of rows to generate (default: 100) |
| 15 | `$COLUMNS`: Specific columns or fields to include |
| 16 | `$FORMAT`: Output format (CSV, JSON, SQL, Python script) |
| 17 | `$CONSTRAINTS`: Additional constraints or business rules |
| 18 | |
| 19 | ## Step-by-Step Process |
| 20 | |
| 21 | **Identify dataset type** - Understand the data domain |
| 22 | **Define column specifications** - Names, data types, and value ranges |
| 23 | **Determine row count** - How many sample records needed |
| 24 | **Select output format** - CSV, JSON, SQL INSERT, or Python script |
| 25 | **Apply realistic patterns** - Ensure data looks authentic and valid |
| 26 | **Add business constraints** - Respect business logic and relationships |
| 27 | **Generate or script data** - Create executable output |
| 28 | **Validate output** - Ensure data quality and completeness |
| 29 | |
| 30 | ## Template: Python Script Output |
| 31 | |
| 32 | |
| 33 | import csv |
| 34 | import json |
| 35 | from datetime import datetime, timedelta |
| 36 | import random |
| 37 | |
| 38 | # Configuration |
| 39 | ROWS = $ROWS |
| 40 | FILENAME = "$DATASET_TYPE.csv" |
| 41 | |
| 42 | # Column definitions with realistic value generators |
| 43 | columns = { |
| 44 | "id": "auto-increment", |
| 45 | "name": "first_last_name", |
| 46 | "email": "email", |
| 47 | "created_at": "timestamp", |
| 48 | # Add more columns... |
| 49 | } |
| 50 | |
| 51 | def generate_dataset(): |
| 52 | """Generate realistic dummy dataset""" |
| 53 | data = [] |
| 54 | for i in range(1, ROWS + 1): |
| 55 | record = { |
| 56 | "id": f"U{i:06d}", |
| 57 | # Generate values based on column definitions |
| 58 | } |
| 59 | data.append(record) |
| 60 | return data |
| 61 | |
| 62 | def save_as_csv(data, filename): |
| 63 | """Save dataset as CSV""" |
| 64 | with open(filename, 'w', newline='') as f: |
| 65 | writer = csv.DictWriter(f, fieldnames=data[0].keys()) |
| 66 | writer.writeheader() |
| 67 | writer.writerows(data) |
| 68 | |
| 69 | if __name__ == "__main__": |
| 70 | dataset = generate_dataset() |
| 71 | save_as_csv(dataset, FILENAME) |
| 72 | print(f"Generated {len(dataset)} records in {FILENAME}") |
| 73 | |
| 74 | |
| 75 | ## Example Dataset Specification |
| 76 | |
| 77 | **Dataset Type:** Customer Feedback |
| 78 | |
| 79 | **Columns:** |
| 80 | feedback_id (auto-increment, U001, U002...) |
| 81 | customer_name (realistic names) |
| 82 | email (valid email format) |
| 83 | feedback_date (dates last 90 days) |
| 84 | rating (1-5 stars) |
| 85 | category (Bug, Feature Request, Complaint, Praise) |
| 86 | text (realistic feedback) |
| 87 | product (electronics, clothing, home) |
| 88 | |
| 89 | **Constraints:** |
| 90 | Ratings skewed: 40% 5-star, 30% 4-star, 20% 3-star, 10% 1-2 star |
| 91 | Bug category only with ratings 1-3 |
| 92 | Feature requests only with ratings 3-5 |
| 93 | Email domains realistic (gmail, yahoo, company.com) |
| 94 | |
| 95 | ## Output Deliverables |
| 96 | |
| 97 | Ready-to-execute Python script OR direct data file |
| 98 | CSV file with proper headers and formatting |
| 99 | JSON file with valid structure and types |
| 100 | SQL INSERT statements for database population |
| 101 | Data validation and constraint compliance |
| 102 | Realistic, business-appropriate values |
| 103 | Documentation of data generation logic |
| 104 | Quick-start instructions for using the dataset |
| 105 | |
| 106 | ## Output Formats |
| 107 | |
| 108 | **CSV:** Flat tabular format, easy to import into spreadsheets and databases |
| 109 | |
| 110 | **JSON:** Nested structure, ideal for APIs and NoSQL databases |
| 111 | |
| 112 | **SQL:** INSERT statements, directly executable on relational databases |
| 113 | |
| 114 | **Python Script:** Executable generator for custom or large datasets |
| 115 |
Details
- Updated
- Sep 14, 2026
- License
- MIT
- Stars on the repo
- ★ 26,557
- Checked
- Source
- phuryn/pm-skills ↗
- Creator
- phuryn · 69 listings
Similar skills
See all → SkillGenome Query: 1000 Genomes
 K-Dense-AI/scientific-agent-skills · by K-Dense-AIQuery the 1000 Genomes Project dataset (3,202 whole-genome-sequenced individuals, GRCh38) at the level of individual participants. Use when a question is about individuals or variants in the 1000 Genomes Project cohort: which individuals carry variants matching specific criteria in a gene or region, which individuals are homozygous-reference at a position, which variants exist in the dataset or carried by specified individuals in a gene or region, the relatedness between two specified individuals. Variants are returned with 1000 Genomes allele frequencies (AF), gnomAD v4.1 exome and genome AF, AlphaMissense score, and HGVSp annotations.★ 46k GitHub stars
 SkillBayesian Modeling FrameworkK-Dense-AI/scientific-agent-skills · by K-Dense-AIBayesian modeling with PyMC. Build hierarchical models, MCMC (NUTS), variational inference, LOO/WAIC comparison, posterior checks, for probabilistic programming and inference.★ 46k GitHub stars
 SkillStatistical Modeling LibraryK-Dense-AI/scientific-agent-skills · by K-Dense-AIStatistical models library for Python. Use when you need specific model classes (OLS, GLM, mixed models, ARIMA) with detailed diagnostics, residuals, and inference. Best for econometrics, time series, rigorous inference with coefficient tables. For guided statistical test selection with APA reporting use statistical-analysis.★ 46k GitHub stars
 SkillHugging Face TransformersK-Dense-AI/scientific-agent-skills · by K-Dense-AIHugging Face Transformers for loading Hub models, running pipeline inference, text generation, and Trainer fine-tuning on NLP, vision, audio, and multimodal tasks. Use when working with AutoModel, pipelines, tokenizers, or TrainingArguments—not for general ML outside the Transformers library.★ 46k GitHub stars
 SkillWaypoint Microbiome ModelsK-Dense-AI/scientific-agent-skills · by K-Dense-AIUse when working with Outpost Bio's open microbiome foundation models - the Waypoint checkpoints (Waypoint-6m, Waypoint-45m, Waypoint-170m), the Atlas pretraining corpus, the Compass eight-task benchmark, or the `waypoint` CLI from the `waypoint-bio` package. Covers embedding microbiome samples, fine-tuning on taxonomic abundance data, benchmarking a checkpoint on Compass, pretraining a GPT-2 model on taxonomic abundance profiles, and converting MetaPhlAn, Kraken2, QIIME 2, or MGnify abundance tables into waypoint format.★ 46k GitHub stars
 SkillTrading Backtest Framework
 wshobson/agents · by wshobsonBuild robust backtesting systems for trading strategies with proper handling of look-ahead bias, survivorship bias, and transaction costs. Use when developing trading algorithms, validating strategies, or building backtesting infrastructure.★ 39.9k GitHub stars
More from phuryn
 SkillA/B Test Analyzer
 phuryn/pm-skills · by phurynAnalyze A/B test results with statistical significance, sample size validation, confidence intervals, and ship/extend/stop recommendations. Use when evaluating experiment results, checking if a test reached significance, interpreting split test data, or deciding whether to ship a variant.★ 26.6k GitHub stars
 SkillFeature Request Prioritizerphuryn/pm-skills · by phurynAnalyze and prioritize a list of feature requests by theme, strategic alignment, impact, effort, and risk. Use when reviewing customer feature requests, triaging a backlog, or making prioritization decisions.★ 26.6k GitHub stars
 SkillAnsoff Matrix Generatorphuryn/pm-skills · by phurynGenerate an Ansoff Matrix analysis mapping growth strategies across market penetration, market development, product development, and diversification. Use when considering growth options, planning market expansion, or evaluating strategic growth paths.★ 26.6k GitHub stars
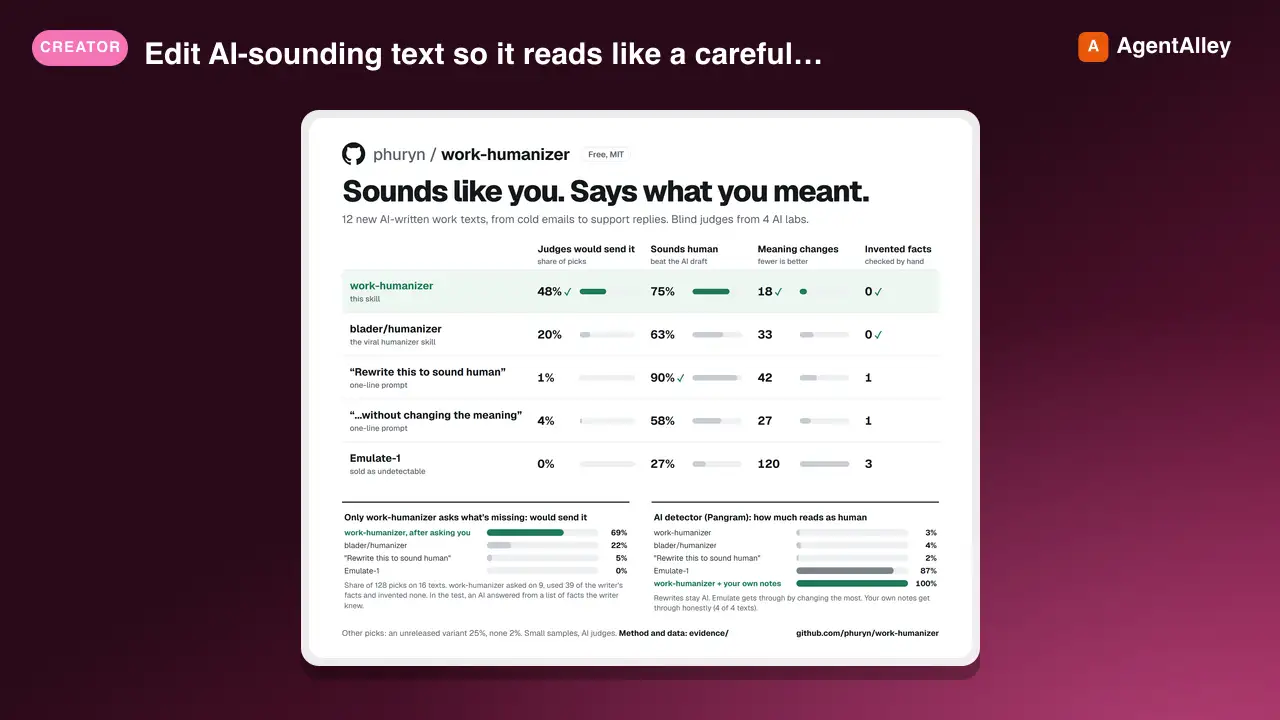 SkillAI Text Humanizerphuryn/work-humanizer · by phurynEdit AI-sounding text so it reads like a careful person wrote it, without changing what it says or commits to. Built for work writing where the wording matters: sales and marketing copy, support replies, HR and legal letters, emails, docs, release notes, posts, landing pages. Two modes. Rewrite: edit the text you are given. Interview: when a draft is AI-composed and thin, ask the writer 3-5 sharp questions and build the piece from their answers, in their words. Also writes from the writer's own notes or a voice-memo transcript. Calibrated on measured differences between human and AI writing.★ 110 GitHub stars
 SkillMarket Segment Identifierphuryn/pm-skills · by phurynIdentify the first beachhead market segment for a product launch. Evaluates segments against burning pain, willingness to pay, winnable market share, and referral potential. Use when choosing a first market, targeting an initial customer segment, or planning market entry strategy.★ 26.6k GitHub stars
 SkillProduct Experiment Designerphuryn/pm-skills · by phurynDesign experiments to test assumptions for an existing product — prototypes, A/B tests, spikes, and other low-effort validation methods. Use when validating assumptions, testing feature ideas cheaply, or planning product experiments.★ 26.6k GitHub stars