B2B Data Cleaner
Clean data
Data cleaning, entity matching, and deduplication skill for Claude Code and Codex: triage, standardize, and validate a CSV, Excel, or JSON list of B2B companies or contacts before enrichment. Normalizes company names and domains,…
---
name: clean-data
description: "Data cleaning, entity matching, and deduplication skill for Claude Code and Codex: triage, standardize, and validate a CSV, Excel, or JSON list of B2B companies or contacts before enrichment. Normalizes company names and domains, validates emails and phone numbers, matches and deduplicates records, and tags invalid rows non-destructively. Run before enrichment or CRM import to avoid paying for noisy records. Use for CRM enrichment prep, company name and website matching, entity matching, and contact deduplication. Works in Claude Code, Codex, and n8n via MCP."
---

# Clean Data

Per-row cleanup on a GTM list before any match or enrich call. Profile, standardize, validate. Never destructive: raw input is preserved, invalid rows are tagged with reason codes rather than deleted. Out of scope: deduplication and canonical entity resolution.

## Input

`$ARGUMENTS` is a path to a CSV, Excel, or JSON file. Parse the user message for optional sub-inputs:

- Schema hints if column names are ambiguous: which column is company name, domain, email, phone, country.
- Entity type: companies, contacts, or both. Default: infer from columns.
- Whether to run an MX-record check on email domains (slower, requires DNS). Default: off.
- Whether to produce a match-ready subset for downstream entity resolution. Default: no.
Overview
Per-row cleanup on a GTM list before any match or enrich call. Profile, standardize, validate. Never destructive: raw input is preserved, invalid rows are tagged with reason codes rather than deleted. Out of scope: deduplication and canonical entity resolution.
Manual install (npx, ZIP)
npx skills add explorium-ai/gtm-skills --skill clean-data -g -a claude-codenpx degit explorium-ai/gtm-skills/skills/clean-data#main ~/.claude/skills/clean-dataConnects with Agent Alley MCP · agentalley.io/mcp
Files included
SKILL.md7.8 KB
Read SKILL.md here
Show the full text98 lines
Clean Data
Per-row cleanup on a GTM list before any match or enrich call. Profile, standardize, validate. Never destructive: raw input is preserved, invalid rows are tagged with reason codes rather than deleted. Out of scope: deduplication and canonical entity resolution.
Input
$ARGUMENTS is a path to a CSV, Excel, or JSON file. Parse the user message for optional sub-inputs:
- Schema hints if column names are ambiguous: which column is company name, domain, email, phone, country.
- Entity type: companies, contacts, or both. Default: infer from columns.
- Whether to run an MX-record check on email domains (slower, requires DNS). Default: off.
- Whether to produce a match-ready subset for downstream entity resolution. Default: no.
Example phrasings:
- "Clean this leads CSV before I import it to HubSpot."
- "Normalize the company names and domains in /path/accounts.xlsx."
- "Validate the emails in this file and tag the bad rows."
- "Prep this list for prospect matching, only keep contactable corporate rows."
- "Why does my country column have 200 different spellings."
Workflow
Copy raw input. Before any transform, copy the input to
./00_raw/<filename>and never write back. All transforms write to numbered phase folders:01_profiled/,02_standardized/,03_validated/. The single most common failure mode in cleanup work is destructive transforms with no path back.Profile the file. Compute fill rate, cardinality, top values, length distribution, and format-pattern frequency for every column. Save the snapshot. Read it before deciding what to clean.
import pandas as pd
df = pd.read_csv(input_path)
profile = pd.DataFrame({
    "fill_rate_pct": (df.notna().mean() * 100).round(1),
    "cardinality": df.nunique(),
    "top_value": df.apply(lambda c: c.dropna().astype(str).mode().iloc[0] if c.dropna().size else None),
    "avg_len": df.apply(lambda c: c.dropna().astype(str).str.len().mean()),
})
Things to look for: country columns with 200+ distinct values (standardization problem, build ISO Alpha-2 lookup); phone columns where under 50% parse as E.164 (need country hint); company-name 99th-percentile length above 100 chars (pasted addresses, quarantine); free-email providers in the top 5 of email column (decide policy now); fields under 10% fill (probably not worth normalizing); literal strings
"NA","N/A","None","null","-"(collapse to real nulls before validating).Standardize string fields. Run standardization BEFORE validation: a valid email like
JOHN@ACME.COMfails naive regex without trim+lowercase first. For every string column do Unicode NFKC, trim, collapse internal whitespace, strip leading and trailing punctuation, collapse null-token strings to real nulls. Then field-specific:- Company name. Strip legal suffixes (
Inc,LLC,Ltd,GmbH,S.A.,株式会社) at end of string only. Usecleancoif available. Keep BOTH raw and normalized columns. - Domain. Strip protocol and
www. Fold to the eTLD+1 viatldextract. Flag free-email providers and disposable domains separately. - Person name. Parse with
nameparser: honorifics, generational suffixes, credentials, particles. If confidence is low, store the raw string with a low-confidence flag. - Phone. Format to E.164 with
phonenumbers. Hint country from the country column when available. - Country. Map free-text to ISO Alpha-2 codes (
United StatestoUS,UKtoGB,DeutschlandtoDE). Reusable downstream for country filters. - Address. Use
libpostalif installed. Country-aware parsing.
Common mistake: overwriting the display column with the normalized version. Always keep raw alongside normalized.
- Company name. Strip legal suffixes (
Validate field-by-field. Per field, add a boolean
<field>_validand a<field>_reasontext column when invalid. Tag invalid rows; never delete them.- Emails: RFC 5322 syntax via
email-validator; role-address detection (info@,sales@,noreply@,support@,hello@); disposable-domain check; free-provider flag (gmail,yahoo,qq); optional MX-record check (off by default). - Phones: parse + format via
phonenumbers. Taginvalid_too_short,invalid_country,invalid_format. - Domains: valid eTLD, no IP literals, optional MX check.
- Country codes: valid ISO Alpha-2 after normalization.
- Emails: RFC 5322 syntax via
Hand off to entity resolution (optional). This skill cleans rows in isolation; it cannot tell you that
Starbucks EMEAandStarbucks Corporationpoint to the same company. If the user wants the handoff, produce a match-ready subset and route rows by available signal:- Rows with normalized company name + domain: route to match a business (name + website, falls back to domain-only on mismatch).
- Rows with a corporate (not role / free-provider / disposable) email: route to match a prospect via email.
- Rows with parsed person name + company name: route to match a prospect via name + company.
- Rows with a validated LinkedIn URL: route to match a prospect via LinkedIn.
Filter out tagged-invalid rows before the handoff so you do not spend credits matching
noreply@example.comor disposable addresses. The returned IDs become the join keys for any later enrich a business or enrich a prospect call.
Output Format
Profile Snapshot
Per column: fill_rate_pct, cardinality, top_value, avg_len. Markdown table. After cleanup, re-run the profile and show before vs after on touched columns.
Standardization Map
Per normalized field: raw column name, normalized column name, 3 to 5 example transformations (" ACME, Inc. " to acme, "WWW.Acme.COM" to acme.com, "+1 (415) 555 1212" to +14155551212).
Validation Verdict
Per validated field: counts of valid, invalid, risky. Frequency table of reason codes (e.g. role_address: 42, disposable_domain: 18, invalid_syntax: 6).
Cleaned File
A single CSV at ./03_validated/<input_name>_clean.csv with all original columns plus <field>_norm, <field>_valid, and <field>_reason columns.
Match-Ready Subset (only if requested)
A second CSV at ./04_match_ready/<input_name>_for_match.csv containing only rows that passed validation, plus a one-line summary of which match path each row subset should route to (count by path).
Limitations
- Does NOT deduplicate or resolve to canonical entities. Two normalized strings can still refer to the same real-world business. Hand off to a match step for that.
- Person-name parsing is best-effort. Non-Western order, hyphenated families, and missing separators are flagged with a low-confidence marker; raw string is always preserved.
- The MX-record check requires DNS and adds 50 to 200ms per unique domain. Off by default.
- Free-email providers (gmail, yahoo) are flagged but cannot be linked to a corporate identity from this skill alone. Pair with a prospect match (email + company) when needed.
- Holding-company and subsidiary pitfalls are out of scope (
meta.comvsinstagram.comvswhatsapp.com). Resolve via company-hierarchies enrichment after matching. - If the input lacks a country column entirely, phone normalization defaults to a permissive parser and may mis-format short numbers. Provide a default country in the user message when possible.
| 1 | |
| 2 | name clean-data |
| 3 | description "Data cleaning, entity matching, and deduplication skill for Claude Code and Codex: triage, standardize, and validate a CSV, Excel, or JSON list of B2B companies or contacts before enrichment. Normalizes company names and domains, validates emails and phone numbers, matches and deduplicates records, and tags invalid rows non-destructively. Run before enrichment or CRM import to avoid paying for noisy records. Use for CRM enrichment prep, company name and website matching, entity matching, and contact deduplication. Works in Claude Code, Codex, and n8n via MCP." |
| 4 | |
| 5 | |
| 6 | # Clean Data |
| 7 | |
| 8 | Per-row cleanup on a GTM list before any match or enrich call. Profile, standardize, validate. Never destructive: raw input is preserved, invalid rows are tagged with reason codes rather than deleted. Out of scope: deduplication and canonical entity resolution. |
| 9 | |
| 10 | ## Input |
| 11 | |
| 12 | `$ARGUMENTS` is a path to a CSV, Excel, or JSON file. Parse the user message for optional sub-inputs: |
| 13 | |
| 14 | Schema hints if column names are ambiguous: which column is company name, domain, email, phone, country. |
| 15 | Entity type: companies, contacts, or both. Default: infer from columns. |
| 16 | Whether to run an MX-record check on email domains (slower, requires DNS). Default: off. |
| 17 | Whether to produce a match-ready subset for downstream entity resolution. Default: no. |
| 18 | |
| 19 | Example phrasings: |
| 20 | |
| 21 | "Clean this leads CSV before I import it to HubSpot." |
| 22 | "Normalize the company names and domains in /path/accounts.xlsx." |
| 23 | "Validate the emails in this file and tag the bad rows." |
| 24 | "Prep this list for prospect matching, only keep contactable corporate rows." |
| 25 | "Why does my country column have 200 different spellings." |
| 26 | |
| 27 | ## Workflow |
| 28 | |
| 29 | **Copy raw input.** Before any transform, copy the input to `./00_raw/<filename>` and never write back. All transforms write to numbered phase folders: `01_profiled/`, `02_standardized/`, `03_validated/`. The single most common failure mode in cleanup work is destructive transforms with no path back. |
| 30 | |
| 31 | **Profile the file.** Compute fill rate, cardinality, top values, length distribution, and format-pattern frequency for every column. Save the snapshot. Read it before deciding what to clean. |
| 32 | |
| 33 | |
| 34 | import pandas as pd |
| 35 | df = pd.read_csv(input_path) |
| 36 | profile = pd.DataFrame({ |
| 37 | "fill_rate_pct": (df.notna().mean() * 100).round(1), |
| 38 | "cardinality": df.nunique(), |
| 39 | "top_value": df.apply(lambda c: c.dropna().astype(str).mode().iloc[0] if c.dropna().size else None), |
| 40 | "avg_len": df.apply(lambda c: c.dropna().astype(str).str.len().mean()), |
| 41 | }) |
| 42 | |
| 43 | |
| 44 | Things to look for: country columns with 200+ distinct values (standardization problem, build ISO Alpha-2 lookup); phone columns where under 50% parse as E.164 (need country hint); company-name 99th-percentile length above 100 chars (pasted addresses, quarantine); free-email providers in the top 5 of email column (decide policy now); fields under 10% fill (probably not worth normalizing); literal strings `"NA"`, `"N/A"`, `"None"`, `"null"`, `"-"` (collapse to real nulls before validating). |
| 45 | |
| 46 | **Standardize string fields.** Run standardization BEFORE validation: a valid email like ` JOHN@ACME.COM ` fails naive regex without trim+lowercase first. For every string column do Unicode NFKC, trim, collapse internal whitespace, strip leading and trailing punctuation, collapse null-token strings to real nulls. Then field-specific: |
| 47 | |
| 48 | **Company name.** Strip legal suffixes (`Inc`, `LLC`, `Ltd`, `GmbH`, `S.A.`, `株式会社`) at end of string only. Use `cleanco` if available. Keep BOTH raw and normalized columns. |
| 49 | **Domain.** Strip protocol and `www`. Fold to the eTLD+1 via `tldextract`. Flag free-email providers and disposable domains separately. |
| 50 | **Person name.** Parse with `nameparser`: honorifics, generational suffixes, credentials, particles. If confidence is low, store the raw string with a low-confidence flag. |
| 51 | **Phone.** Format to E.164 with `phonenumbers`. Hint country from the country column when available. |
| 52 | **Country.** Map free-text to ISO Alpha-2 codes (`United States` to `US`, `UK` to `GB`, `Deutschland` to `DE`). Reusable downstream for country filters. |
| 53 | **Address.** Use `libpostal` if installed. Country-aware parsing. |
| 54 | |
| 55 | Common mistake: overwriting the display column with the normalized version. Always keep raw alongside normalized. |
| 56 | |
| 57 | **Validate field-by-field.** Per field, add a boolean `<field>_valid` and a `<field>_reason` text column when invalid. Tag invalid rows; never delete them. |
| 58 | |
| 59 | **Emails:** RFC 5322 syntax via `email-validator`; role-address detection (`info@`, `sales@`, `noreply@`, `support@`, `hello@`); disposable-domain check; free-provider flag (`gmail`, `yahoo`, `qq`); optional MX-record check (off by default). |
| 60 | **Phones:** parse + format via `phonenumbers`. Tag `invalid_too_short`, `invalid_country`, `invalid_format`. |
| 61 | **Domains:** valid eTLD, no IP literals, optional MX check. |
| 62 | **Country codes:** valid ISO Alpha-2 after normalization. |
| 63 | |
| 64 | **Hand off to entity resolution (optional).** This skill cleans rows in isolation; it cannot tell you that `Starbucks EMEA` and `Starbucks Corporation` point to the same company. If the user wants the handoff, produce a match-ready subset and route rows by available signal: |
| 65 | |
| 66 | Rows with normalized company name + domain: route to **match a business** (name + website, falls back to domain-only on mismatch). |
| 67 | Rows with a corporate (not role / free-provider / disposable) email: route to **match a prospect** via email. |
| 68 | Rows with parsed person name + company name: route to **match a prospect** via name + company. |
| 69 | Rows with a validated LinkedIn URL: route to **match a prospect** via LinkedIn. |
| 70 | |
| 71 | Filter out tagged-invalid rows before the handoff so you do not spend credits matching `noreply@example.com` or disposable addresses. The returned IDs become the join keys for any later **enrich a business** or **enrich a prospect** call. |
| 72 | |
| 73 | ## Output Format |
| 74 | |
| 75 | ### Profile Snapshot |
| 76 | Per column: `fill_rate_pct`, `cardinality`, `top_value`, `avg_len`. Markdown table. After cleanup, re-run the profile and show before vs after on touched columns. |
| 77 | |
| 78 | ### Standardization Map |
| 79 | Per normalized field: raw column name, normalized column name, 3 to 5 example transformations (`" ACME, Inc. "` to `acme`, `"WWW.Acme.COM"` to `acme.com`, `"+1 (415) 555 1212"` to `+14155551212`). |
| 80 | |
| 81 | ### Validation Verdict |
| 82 | Per validated field: counts of valid, invalid, risky. Frequency table of reason codes (e.g. `role_address: 42`, `disposable_domain: 18`, `invalid_syntax: 6`). |
| 83 | |
| 84 | ### Cleaned File |
| 85 | A single CSV at `./03_validated/<input_name>_clean.csv` with all original columns plus `<field>_norm`, `<field>_valid`, and `<field>_reason` columns. |
| 86 | |
| 87 | ### Match-Ready Subset (only if requested) |
| 88 | A second CSV at `./04_match_ready/<input_name>_for_match.csv` containing only rows that passed validation, plus a one-line summary of which match path each row subset should route to (count by path). |
| 89 | |
| 90 | ## Limitations |
| 91 | |
| 92 | Does NOT deduplicate or resolve to canonical entities. Two normalized strings can still refer to the same real-world business. Hand off to a match step for that. |
| 93 | Person-name parsing is best-effort. Non-Western order, hyphenated families, and missing separators are flagged with a low-confidence marker; raw string is always preserved. |
| 94 | The MX-record check requires DNS and adds 50 to 200ms per unique domain. Off by default. |
| 95 | Free-email providers (gmail, yahoo) are flagged but cannot be linked to a corporate identity from this skill alone. Pair with a prospect match (email + company) when needed. |
| 96 | Holding-company and subsidiary pitfalls are out of scope (`meta.com` vs `instagram.com` vs `whatsapp.com`). Resolve via company-hierarchies enrichment after matching. |
| 97 | If the input lacks a country column entirely, phone normalization defaults to a permissive parser and may mis-format short numbers. Provide a default country in the user message when possible. |
| 98 |
Details
- License
- MIT
- Stars on the repo
- ★ 197
- Checked
- Source
- explorium-ai/gtm-skills ↗
- Creator
- explorium-ai · 17 listings
Similar skills
See all → AgentNEXUS Quick-Start Guide
 msitarzewski/agency-agents · by msitarzewski> Get from zero to orchestrated multi-agent pipeline in 5 minutes.★ 154k GitHub stars
 SkillRaw Footage Cleanup
 hassancs91/claude-youtube-editor · by hassancs91Step 1 of the AI Video Editor pipeline — turn raw talking-head footage into a clean master cut. Use when the user wants to "clean cut", "cut the raw footage", "remove filler / dead air / bad takes", "tighten the pacing", produce cuts.json, run the cut editor, or render a cleaned preview/master for a video-N project in this repo. Covers audio extraction, AssemblyAI transcription, authoring cuts.json (keeps/cuts/fluff categorized), the cut policy (content-aggressive, pause-natural ~0.5s), QA + review docs, the local cut-editor UI, tight/natural previews, the final 4K60 render, and producing edited-transcript.json as the handoff to /make-tsx. Not for building TSX overlays (that is /make-tsx) or the raw TSX authoring rules (that is vidtsx-2d-generator).★ 330 GitHub stars
 SkillVocaloid Music Video Builder
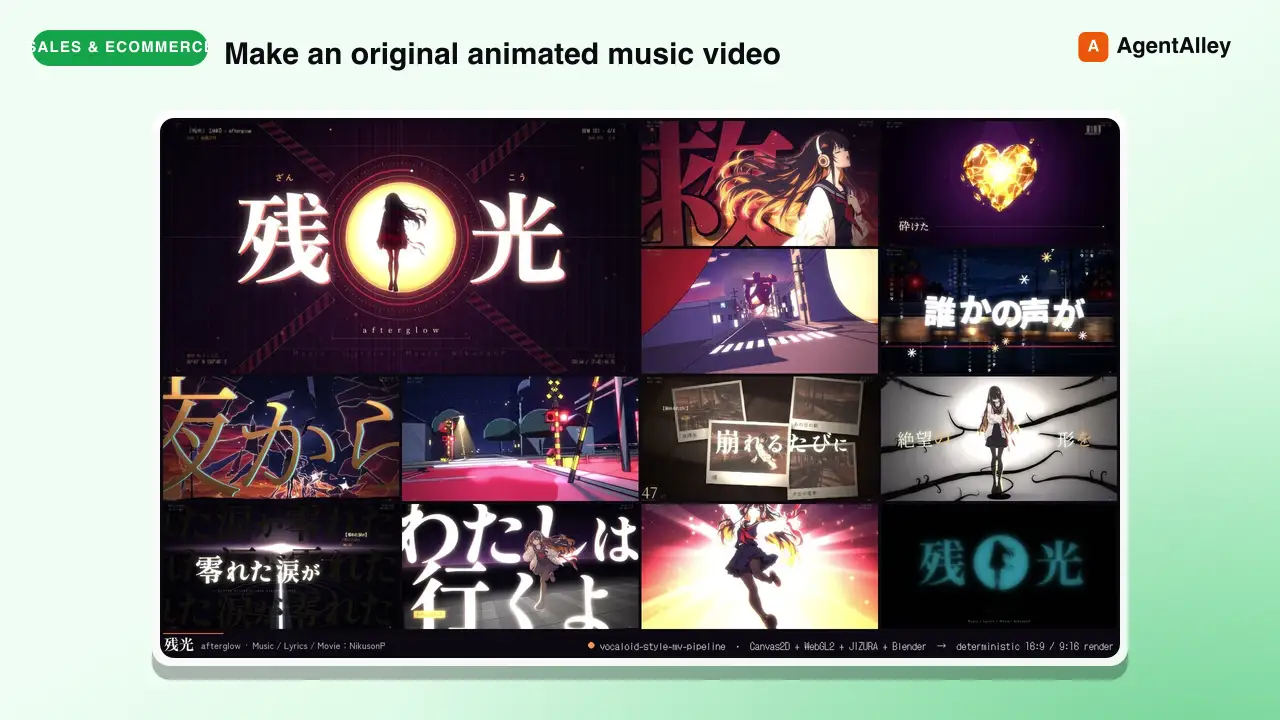
 EGSECDA/vocaloid-style-mv-pipeline · by EGSECDAMake an original animated music video (MV / PV) for a song from its audio file plus lyrics, in the Vocaloid / J-pop lyric-video tradition: 手書き/tegaki (V家手书, 手描きMV, ボカロPV), 文字PV and kinetic typography (リリックモーション, リリックビデオ, 歌詞動画, 歌词视频, 动态歌词), anime-illustration MVs with an original character — for any mood, from dark ballads to bright upbeat summer pop. Renders to MP4 with a deterministic Canvas2D/WebGL2 engine in a headless browser: JIZURA lyric motion, AI-generated art, optional Blender toon 3D, beat-locked editing, 9:16 vertical/Shorts version. Use it whenever the user wants a music video, MV, PV, lyric video or beat-synced animation for a song, e.g. make an MV for my song", "turn this track into a lyric video", "给这首歌做个MV/PV", "做个V家手书", "この曲のMVを作って", ボカロPV作って", "縦型ショートも" — even if they only give a .wav/.mp3 and say "make a cool video for it". Not for editing existing footage or clip compilations.★ 169 GitHub stars
 SkillConstruction Project Manager
 hewi333/Mom-n-Pop-Skills · by hewi333Construction company AI agent — orchestrates email (Google Workspace), project management (JobTread Pave API), and file routing for a construction business. Handles email triage, attachment routing to JobTread, project status, task management, and daily briefings via Telegram. Reference implementation for a construction/trades business with an existing email→Drive→PM pipeline.★ 122 GitHub stars
 SkillLightweight SQLite CRMhewi333/Mom-n-Pop-Skills · by hewi333Use when tracking customer interactions, managing leads, or building a lightweight CRM for small businesses without dedicated CRM software. Stores contacts, leads, activities, estimates, and communications in local SQLite.★ 122 GitHub stars
 SkillShort Video Pipeline
 howznguyen/shorts-kit · by howznguyenOrchestrates one narrated vertical short (TikTok, YouTube Shorts, Reels) from idea to upload-ready hand-off files, in the fixed order idea, facts, flow and visual choice, brief, narration, TTS, lint, scenes, still review, render, cover, normalize, encode, hand-off. Use when the user says "make a video about X", "start a new short", "take this idea to a finished video", "what's the next step", "where was I on this video", or asks how the whole pipeline fits together. Also when the user gives a video or audio file (or a folder of clips) to edit: "edit this video", "dựng video này", a .mov/.mp4 path. Points at the skill and the SOUL section that governs each step.★ 69 GitHub stars
More from explorium-ai
 SkillABM Campaign Playbook
 explorium-ai/gtm-skills · by explorium-aiABM campaign skill for Claude Code: run a full Account-Based Marketing campaign end-to-end — from ICP definition to live LinkedIn Ads. Builds targeted account lists with Vibe Prospecting, enriches and scores companies with real-time B2B data, generates personalized ad creatives with Claude Code and Figma, pushes matched audiences to LinkedIn Ads, and monitors campaigns daily at scale. The complete GTM skill for AI-driven account-based marketing in Claude Code, Codex, Hermes-Agent, and OpenClaw. No agency needed.★ 197 GitHub stars
 SkillDecision-Maker Shortlistexplorium-ai/gtm-skills · by explorium-aiContact data skill for Claude Code and Codex: build a ranked shortlist of decision-makers and contacts at a target company for outbound prospecting, deal acceleration, or renewal/expansion plays. Returns verified contact data including email, phone, LinkedIn profile, title, seniority, and department. Provide a company name or domain plus optional seniority focus or use case. Use for contact data enrichment, LinkedIn profile lookup, and building outbound contact lists. Works in Claude Code, Codex, Hermes-Agent, and OpenClaw.★ 197 GitHub stars
 SkillAccount Fit Scorerexplorium-ai/gtm-skills · by explorium-aiLead scoring and buying signals skill for Claude Code and Codex: rank a list of accounts by ICP fit, buying intent, real-time trigger events, and workforce momentum. Returns composite score (0-100), tier (A/B/C), and a 'why now' signal per account. Use for account-based selling, ABM list prioritization, territory planning, signal-based selling, and buyer-intent ranking. Triggers on 'score these accounts', 'rank by ICP fit and intent', 'prioritize this account list', 'which accounts have the strongest buying signals', 'ICP scoring', 'account prioritization'. Works in Claude Code, Codex, Hermes-Agent, OpenClaw, and Claude Cowork.★ 197 GitHub stars
 SkillCompany Intelligence Briefexplorium-ai/gtm-skills · by explorium-aiAccount research skill for Claude Code and Codex: generate a high-signal company intelligence brief including firmographics, technographics, funding history, hiring signals, business events, recent website and LinkedIn moves, and a peer cohort. Identify the account by business_id, company name, or domain. Use for pre-call research, QBR prep, competitive analysis, cold outbound targeting, and renewal risk assessment. The go-to account research skill for Claude Code, Codex, Hermes-Agent, and OpenClaw.★ 197 GitHub stars
 SkillVibe-Lemlist Outreachexplorium-ai/gtm-skills · by explorium-aiCold email skill for Claude Code and Codex: build a targeted B2B prospect list with Vibe Prospecting, enrich it with firmographics and verified work emails, write a personalized icebreaker and email per prospect from their real company data, and push every lead into a live Lemlist campaign with personalization variables pre-filled. Use for cold outbound, email personalization at scale, and Lemlist campaign setup. Triggers on 'cold email campaign', 'push leads to Lemlist', 'write personalized outbound emails', 'build a Lemlist sequence'. Works in Claude Code, Codex, Grok, and Claude Cowork.★ 197 GitHub stars
 SkillContact Profile Enricherexplorium-ai/gtm-skills · by explorium-aiContact research skill for Claude Code and Codex: given a list of people, match and enrich each one with Vibe Prospecting — verified work email, LinkedIn, direct phone, current role, work history, seniority, and recent job changes — then write a 4-6 sentence professional synopsis per person. Use for pre-call research, account intelligence, founder diligence, recruiting, and conference prep. Triggers on 'research these people', 'profile this contact list', 'who are these attendees', 'background on these prospects'. Works in Claude Code, Codex, Grok, and Claude Cowork.★ 197 GitHub stars